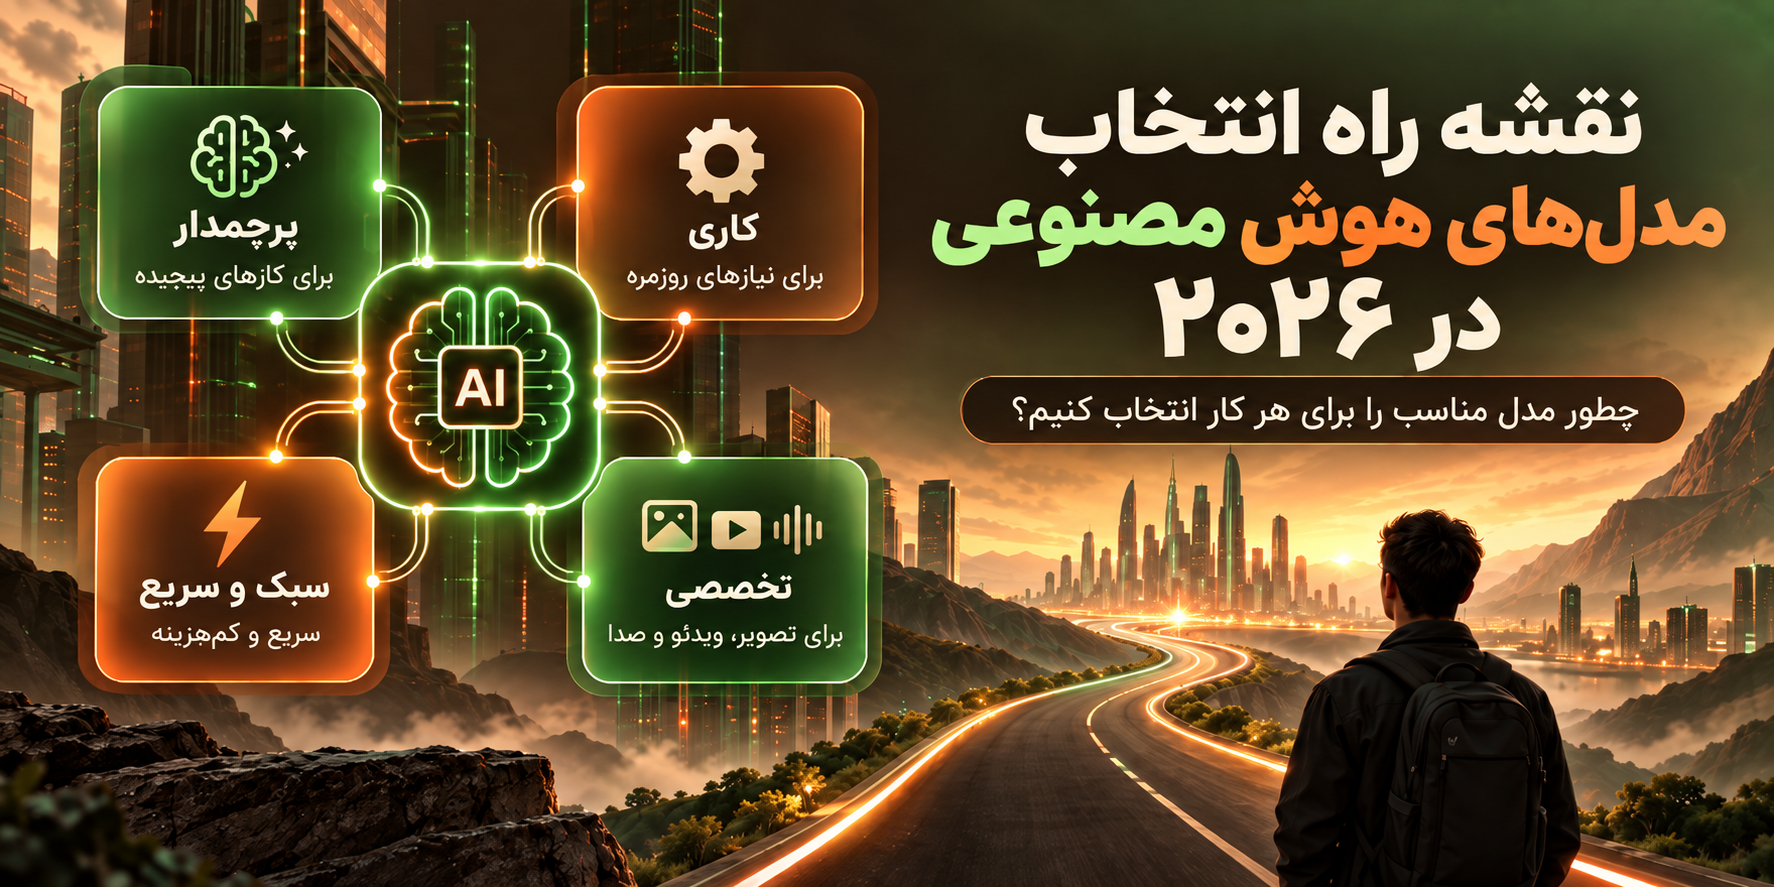
How to Choose the Right AI Model in 2026: Which Model Is Best for Each Task?
Just a few years ago, choosing an AI model was relatively straightforward. There were only a handful of well-known options, and most users simply had to decide between platforms such as ChatGPT, Claude, or Gemini.
In 2026, the landscape looks very different.
Today, we have model families such as GPT-6, Claude 5.5, Gemini 3, Grok 4, DeepSeek V4, Gemma 4, along with dozens of specialized AI models for image generation, video, audio, music, coding, and automation.
That means the real question is no longer:
“What is the best AI model?”
A much more useful question is:
“Which AI model is the best fit for the task I actually need to accomplish?”
A model may be exceptionally good at solving complex reasoning problems but still be unnecessarily expensive for summarizing hundreds of documents every day. Another model might not lead every reasoning benchmark, yet deliver far better value for automation because it is faster and considerably cheaper.
And if your goal is to generate images, video, or music, using a general-purpose language model may not even be the most effective approach.
The core idea behind choosing AI models therefore remains simple: first identify the type of task you need to perform, then choose a model whose capabilities, speed, and cost match that task.
In practical terms, most AI models can be grouped into four broad categories:
-
Flagship or frontier models
-
Workhorse models
-
Light and fast models
-
Specialized models
The boundaries between these groups are becoming less rigid, but the framework still provides a useful way to understand the market.
The Most Important Rule in 2026: Choose the Model Based on the Task, Not the Brand
The rapid evolution of AI models has made the idea of a single “best model” increasingly misleading.
Even AI companies themselves no longer rely on one model for every use case.
OpenAI offers different tiers within the GPT-6 family. Anthropic distinguishes between Opus, Sonnet, and lighter models. Google follows a similar approach with Pro, Flash, and Flash-Lite models.
The message is clear:
A more powerful model is not automatically a better model for your particular task.
Imagine that you need to classify thousands of product descriptions every day. Using the most expensive frontier model available would probably increase your costs without creating a meaningful improvement in the final result.
But if you are redesigning a large software architecture, performing complex research across multiple sources, or building an agent that must independently complete a long sequence of tasks, paying for a more capable model can make much more sense.
A useful way to categorize current AI models is the following:
| Model Category | Best For | Main Priority | Current Examples |
|---|---|---|---|
| Flagship / Frontier | Complex reasoning, research, advanced coding, sophisticated agents | Maximum capability | GPT-6 Astra, Claude Opus 5.5, Gemini 3.1 Pro Preview |
| Workhorse | Most professional everyday tasks | Balance of quality, speed, and cost | GPT-6 Sol, Claude Sonnet 5.5, Gemini 3.8 Flash, Grok 4.7 |
| Light & Fast | Automation, high-volume processing, repetitive tasks | Speed and cost efficiency | GPT-6 Luna, DeepSeek V4.1 Flash, Mistral Small 4 |
| Specialized | Image, video, voice, and music generation | Performance on a specific task | GPT-Image 2.5, Nano Banana, Veo, Suno, and similar models |
There is one important caveat: these categories are not absolute.
Some newer AI models have become capable enough to sit somewhere between two categories.
Gemini 3.8 Flash is a good example. The word “Flash” traditionally suggested a lightweight, inexpensive model. Yet Google has positioned Gemini 3.8 Flash for long-running software engineering workflows, agents, and complex enterprise processes as well.
That is why it is better to think in terms of use cases rather than fixed model labels.
Category One: Flagship AI Models for Truly Difficult Problems
Flagship, or frontier, models are designed for situations where reasoning quality, tool use, reliability, and performance on long or complex tasks matter more than the cost of each request.
This is where the additional capability of a larger model can genuinely make a difference.
Analyzing ambiguous problems, migrating a large software project, conducting multi-step research, working across dozens of sources, developing complex plans, or operating an agent over extended workflows are all good examples.
GPT-6 Astra: OpenAI’s Flagship Model
In September 2026, OpenAI introduced GPT-6 Astra as its most capable general-purpose model.
The model is designed for tasks such as computer use, web navigation, software engineering, scientific research, and complex professional workflows.
Its standard API pricing for shorter context workloads is $10 per million input tokens and $50 per million output tokens.
GPT-6 Astra is not the kind of model you necessarily need for writing a short email or generating tags for a blog post.
Its value becomes clearer when the problem is difficult enough that better reasoning, fewer mistakes, or stronger tool use can justify the additional cost.
In other words, GPT-6 Astra makes more sense as a senior specialist than as an everyday assistant.
Claude Opus 5.5: Anthropic’s Heavyweight Model for Complex Work
Anthropic introduced Claude Opus 5.5 on September 22, 2026.
The company positions Opus 5.5 for agentic coding, sophisticated knowledge work, and tasks requiring sustained judgment over long-running processes.
Its API pricing is $4 per million input tokens and $20 per million output tokens.
Anthropic has also said that Opus 5.5 can complete many workloads at roughly 40% lower cost than Opus 5.
One especially useful point is that Anthropic itself has warned against overinterpreting small differences between benchmark scores.
As advanced AI models become more capable, a few percentage points on a benchmark do not necessarily translate into a meaningful difference in your actual workflow.
That lesson applies to almost every AI model comparison:
Use benchmarks as a reference, but test models on your real tasks before making a decision.
Gemini 3.1 Pro: Google’s Advanced Model, Still in Preview
Within Google’s ecosystem, Gemini 3.1 Pro remains one of its advanced Pro-tier models for complex problem solving, software engineering, and agentic workflows.
It supports text, image, video, audio, and PDF inputs and offers a context window of more than one million tokens.
However, at the time of writing, the model is still labeled as Preview.
That distinction matters.
If you are deploying a production system where version stability and predictable behavior are critical, the word “Pro” alone should not automatically make a preview model your first choice.
Category Two: Workhorse Models Are Probably What Most Users Actually Need
In practice, most tasks do not require the most powerful AI model available.
Writing and editing, document analysis, reporting, general research, everyday programming, debugging, presentation creation, data analysis, and many professional workflows can be handled very effectively by a strong workhorse model.
One of the biggest developments in 2026 is just how capable these AI models have become.
For many everyday workloads, the performance gap between workhorse models and flagship models has become much smaller.
GPT-6 Sol: OpenAI’s Main Model for Everyday Complex Work
Within the GPT-6 family, GPT-6 Sol serves as the workhorse model.
Its standard API pricing for shorter context workloads is $2 per million input tokens and $10 per million output tokens, making it considerably less expensive than Astra.
For software development, research, analysis, professional writing, and workflows that require strong capabilities without necessarily involving the hardest possible problems, a model in this category is often a more sensible starting point.
Claude Sonnet 5.5: One of the Latest Changes in the AI Market
One of the most recent changes in this space arrived on September 28, 2026, when Anthropic released Claude Sonnet 5.5.
The model is designed to serve as the workhorse of the Claude family for clearly defined everyday tasks such as writing and editing documents, coding, debugging, and tool use.
Its API pricing remains the same as Sonnet 5: $2 per million input tokens and $10 per million output tokens.
Anthropic says the newer model can complete many tasks using fewer tokens and fewer tool calls.
GitHub also made Sonnet 5.5 available through Copilot on the same day, positioning it for common development work such as implementing features and fixing bugs.
For many professional users, this tier of AI models may offer a more attractive balance of capability and cost than jumping directly to a flagship model.
Gemini 3.8 Flash: When “Flash” No Longer Means Simple
Google released Gemini 3.8 Flash as a stable production-ready model on September 2, 2026.
It supports more than one million tokens of context and accepts text, image, video, audio, and PDF inputs.
It can also work with capabilities such as function calling, search, code execution, and preview versions of computer use.
Its introductory API pricing through December 31, 2026 is $0.75 per million input tokens and $3.75 per million output tokens.
Google has indicated that standard pricing will increase from the beginning of 2027.
For large-document analysis, multimodal workloads, video processing, agent development, and applications requiring very long context windows, Gemini 3.8 Flash is one of the models worth evaluating.
Grok 4.7: xAI’s New Model for Coding and Knowledge Work
Grok 4.7 was released on September 21, 2026.
xAI positions the model for coding, agentic applications, and knowledge work.
It offers a 500,000-token context window. For workloads below 200,000 tokens, API pricing is $2 per million input tokens and $6 per million output tokens.
The model also accepts image inputs.
One common misconception about Grok is that every answer automatically has access to live information from X or the wider web.
According to xAI’s documentation, real-time access requires the relevant Web Search or X Search tools to be enabled.
Category Three: Light and Fast Models for Automation and High-Volume Processing
If you run a request five times per day, model pricing may not matter very much.
If you run that same request 100,000 times per day, choosing the right AI model can have a direct impact on the economics of your product.
Customer-support classification, information extraction, tagging, intent detection, batch processing, autocomplete, short summaries, and many intermediate steps inside AI agents often do not require the most capable model on the market.
This is where lightweight models become particularly useful.
GPT-6 Luna: OpenAI’s Low-Cost Model
GPT-6 Luna is the lower-cost model in the GPT-6 family.
For standard shorter-context API usage, pricing is $0.10 per million input tokens and $0.50 per million output tokens.
That is a dramatic difference compared with Astra and even Sol.
This pricing difference helps explain why architectures that send every request to the most powerful model are often economically inefficient.
A production system could route straightforward tasks to Luna first and escalate only genuinely difficult requests to more capable models.
DeepSeek V4.1 Flash: Strong Focus on Price-to-Performance
DeepSeek released V4.1 Flash on September 10, 2026, replacing the previous V4 Flash model.
The new version offers a one-million-token context window, supports both Thinking and Non-Thinking modes, accepts image inputs, and is available through the API as deepseek-flash.
DeepSeek continues to use peak and off-peak pricing.
For V4.1 Flash, uncached input costs between $0.15 and $0.30 per million tokens depending on the time of use, while output pricing ranges from $0.60 to $1.20 per million tokens.
This pricing structure is especially interesting for non-real-time processing.
Organizations can schedule large batch jobs during cheaper periods and reduce total processing costs.
Mistral Small 4: An Open Model With Low API Costs
Mistral Small 4 was released in March 2026 under the Apache 2.0 license.
The model supports text and image inputs, a 256,000-token context window, adjustable reasoning, agentic capabilities, and coding workflows.
Its API pricing is $0.15 per million input tokens and $0.60 per million output tokens.
An important advantage of Mistral Small 4 is that its model weights are also available.
That makes it relevant not only as a low-cost API model, but also for organizations that want to deploy AI models within their own infrastructure.
AI Model Pricing in 2026: How Large Are the Differences?
The table below highlights the API pricing of several prominent models.
All prices are listed per one million tokens and refer to API usage rather than consumer subscriptions such as ChatGPT Plus or Claude Pro.
| Model | Approximate Category | Input | Output |
|---|---|---|---|
| GPT-6 Astra | Flagship | $10 | $50 |
| Claude Opus 5.5 | Flagship | $4 | $20 |
| GPT-6 Sol | Workhorse | $2 | $10 |
| Claude Sonnet 5.5 | Workhorse | $2 | $10 |
| Grok 4.7 | Workhorse / Frontier | $2 | $6 |
| Gemini 3.8 Flash | Workhorse | $0.75 | $3.75 through the end of 2026 |
| GPT-6 Luna | Light | $0.10 | $0.50 |
| Mistral Small 4 | Light / Open | $0.15 | $0.60 |
| DeepSeek V4.1 Flash | Light | $0.15–$0.30 | $0.60–$1.20 |
The table makes one point very clear:
The price difference between AI models can easily reach tens of times.
But raw token pricing is not the whole story.
If one model needs twice as many tokens to complete the same job, it may ultimately cost more than another model with a higher listed token price.
Caching, batch processing, long context windows, tool calls, retries, and agent duration can all influence your actual costs.
That is why a more useful metric is often:
Cost per successfully completed task
rather than simply the price per million tokens.
Category Four: Specialized AI Models — Not Every Task Needs a General-Purpose LLM
One common mistake when choosing AI models is assuming that a general-purpose language model should handle every kind of task.
In 2026, specialized models for image generation, video, voice, and music have become advanced enough that using a purpose-built model is often the more effective option.
Best AI Models for Image Generation and Editing
Several major ecosystems currently dominate the image-generation market.
OpenAI introduced GPT-Image-2.5 in September 2026.
Within its API, Flare is designed for fast, high-quality everyday generation and editing, while Sunburst focuses on more precise editing and professional creative workflows.
Google has also expanded the Nano Banana family.
Nano Banana 2 serves as the general-purpose model, Nano Banana 2 Lite prioritizes speed and lower cost, while Nano Banana Pro is intended for more complex workflows and professional asset creation.
Google has also announced that Imagen models have been discontinued in the Gemini API, with users expected to migrate to Nano Banana.
Meanwhile, Midjourney V8.2 became Midjourney’s default version in July 2026.
The release focuses on visual quality, aesthetics, personalization, and an updated editing model.
Once again, there is no absolute winner.
Editing an existing image with high precision is a very different task from generating concept art or producing hundreds of consistent advertising assets.
Best AI Models for Video Generation
The generative-video market has also changed significantly in 2026.
Google now positions Gemini Omni Flash as its default option for conversational video generation and editing.
The model can use text, image, audio, and video inputs within a multi-step workflow.
For use cases requiring more precise controls, such as scene extension, first-and-last-frame control, or other specialized workflows, Veo 3.1 remains available.
Veo 3.1 can generate eight-second video clips with native audio at 720p, 1080p, or 4K resolution.
It also supports vertical video, video extension, and reference images.
xAI has added Grok Imagine Video 1.5 for video generation and Imagine Image 2.0 for image generation to its API portfolio as well.
The broader lesson is simple:
If the final output you need is video, you may not need to begin with a language model at all.
A specialized video model can provide a much shorter path from prompt to finished asset.
AI Models for Voice and Music
Google added Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS to its stable Gemini lineup in September 2026.
The former focuses more heavily on voice quality and expressive delivery, while the Lite version is optimized for speed and high-volume processing.
In music generation, Suno v6 launched on September 9, 2026.
The new family includes v6, the more experimental v6-wild, and the faster v6-mini.
New capabilities include editing specific parts of songs using natural-language instructions, mashups, and workflows that can combine text, audio, image, and video inputs.
Google also released Lyria 3.5 publicly in September 2026 and priced the API at $0.08 per request for generating a full song.
If Privacy Matters, Consider Open-Weight Models
Choosing an AI model is not only about quality and API pricing.
Sometimes organizational data is sensitive enough that sending it to a cloud-based model is not desirable.
In other situations, developers may want to fine-tune a model, deploy it without a permanent internet connection, or run it entirely within their own infrastructure.
That is where open-weight models become particularly valuable.
One major option in 2026 is Gemma 4.
Google released the family under the Apache 2.0 license in several sizes ranging from E2B and E4B to 12B, 26B A4B, and 31B.
Smaller models are specifically designed to run on laptops and edge hardware, while larger versions are better suited to workstations and servers.
Depending on the version, Gemma 4 supports text, images, and in some cases audio, with context windows of up to 256,000 tokens.
Mistral Small 4 is another Apache 2.0 model whose weights are publicly available.
It offers another path for private deployment, although running the full model requires considerably more capable hardware than smaller Gemma variants.
DeepSeek has also released weights for models in its V4 family, giving organizations another option for customized deployment.
If privacy is your primary concern, the most useful question may therefore shift from:
“Which API is cheaper?”
to:
“Which model can I run under my own control?”
Which AI Model Should You Choose for Each Use Case?
Now we arrive at the practical part.
You do not need to memorize dozens of benchmark tables to choose an AI model effectively.
You simply need to define the problem correctly.
| Use Case | Logical Starting Point |
|---|---|
| Writing, editing, and everyday professional work | GPT-6 Sol, Claude Sonnet 5.5, or Gemini 3.8 Flash |
| Complex multi-step problems | GPT-6 Astra or Claude Opus 5.5 |
| Everyday coding and debugging | Claude Sonnet 5.5, GPT-6 Sol, Gemini 3.8 Flash, or Grok 4.7 |
| Long-running complex agents | Start with a workhorse model and upgrade to Opus/Astra only when necessary |
| High-volume processing and automation | GPT-6 Luna, DeepSeek V4.1 Flash, or Mistral Small 4 |
| Very large documents and multimodal inputs | Gemini 3.8 Flash |
| Private or local deployment | Gemma 4 or Mistral Small 4 |
| Image generation and editing | GPT-Image-2.5, Nano Banana 2/Pro, or Midjourney V8.2 |
| Video generation | Gemini Omni Flash or Veo 3.1 |
| Music generation | Suno v6 or Lyria 3.5 |
This table should not be treated as a definitive verdict.
Think of it as a starting point.
From there, test two or three models using your own real-world examples.
For instance, if your job involves content creation, take five previously published articles, a brand guideline, and a few recurring tasks. Give the same materials to several models and compare their performance based on tone, accuracy, editing effort, speed, and cost.
That kind of evaluation is much more valuable than a small benchmark difference that may have little relationship to your actual workflow.
A Better Strategy: Use Model Routing Instead of Choosing Only One Model
One of the most important changes in the way companies use AI models is that an entire product or workflow no longer has to depend on a single model.
Imagine you are building a customer-support agent.
Simple tasks such as language detection, topic classification, and extracting an order number could be handled by a lightweight model.
If the customer asks a more complicated question, the request could be routed to a workhorse model.
Only highly ambiguous or genuinely difficult cases would need to reach a flagship model.
The same approach can work for content production.
A low-cost model might extract data and classify sources.
A workhorse model could write the first draft.
A more capable model could be used only for deep analysis, strategic decisions, or resolving conflicts between sources.
The result is usually a system that is both cheaper and more efficient.
In fact, the more useful question in 2026 may no longer be:
“Which AI model should I choose?”
Instead, ask:
“Which model should handle each part of my workflow?”
Six Criteria to Consider When Comparing AI Models
The first criterion is performance on your actual task.
Test models using your own prompts, documents, and business data rather than relying solely on demonstrations from model providers.
The second is the total cost of completing the task.
Token pricing is only one variable. Output length, retries, tool calls, caching, and the total runtime of an agent can all affect the final cost.
The third criterion is speed.
A delay of a few seconds may not matter in an internal research tool, but it can significantly affect the user experience in live chat, autocomplete, or voice-agent applications.
The fourth criterion is context size and supported input types.
If you regularly work with hundreds of pages of documentation, audio files, images, or video, multimodal support and context-window size become much more important.
The fifth factor is tools and ecosystem integration.
Web search, code execution, file search, computer use, function calling, and connectors can sometimes matter more than the model’s raw intelligence.
Finally, consider privacy and deployment options.
For some organizations, an open-weight model running on internal infrastructure may be a better choice than a slightly more capable cloud API.
Is the Newest AI Model Always the Better Choice?
Not necessarily.
A new release does not mean you should immediately migrate every existing workflow to it.
A newer model may follow prompts differently, use tokens differently, or behave inconsistently with an older version on certain specialized tasks.
The distinction between Stable and Preview releases also matters.
For example, Gemini 3.8 Flash is currently considered stable and suitable for production use, while Gemini 3.1 Pro remains in Preview.
Before migrating to a new model, it is better to maintain a set of real-world regression tests and run the new version against the same inputs.
Do Flagship Models Always Produce Better Results?
For the most difficult tasks, they are more likely to.
For simpler tasks, however, the difference may not be large enough to justify the additional cost.
If a model that charges $50 per million output tokens and another model that charges $0.50 can both perform a simple classification task at the level of accuracy you need, using the more expensive option provides little practical benefit.
A flagship model makes sense when its additional capability creates real economic value.
Are Cheap AI Models Good Enough for Content Creation?
For some stages of the content workflow, absolutely.
Lightweight models can work very well for keyword extraction, tagging, content classification, format conversion, simple summarization, and large-scale processing.
However, writing an expert article, interpreting a sophisticated tone of voice, synthesizing conflicting sources, or developing a content strategy usually benefits from a strong workhorse model or, in harder cases, a flagship model.
The best content workflow does not necessarily rely on one AI model.
It may use several models, each for the task it handles best.
Do Regular Users Need to Care About API Pricing?
Not always.
The pricing discussed in this article refers to API access, which matters primarily to developers and organizations integrating AI models into their products, software, or automations.
If you only use ChatGPT, Claude, Gemini, or similar services through their regular interfaces, subscription pricing and usage limits are more relevant.
API pricing and monthly consumer subscriptions are two different things.
Final Thoughts: In 2026, There Is No Single “Best AI Model” — Only the Best Fit
The AI model market in 2026 has reached a point where choosing a model based purely on brand recognition or benchmark rankings is no longer enough.
GPT-6 Astra and Claude Opus 5.5 are designed for extremely demanding tasks, but there is little reason to send every everyday request to them.
Models such as GPT-6 Sol, Claude Sonnet 5.5, Gemini 3.8 Flash, and Grok 4.7 can handle a large share of professional workloads.
For high-volume processing, options such as GPT-6 Luna, DeepSeek V4.1 Flash, and Mistral Small 4 can dramatically reduce costs.
For image, video, voice, and music generation, specialized models are often the more sensible choice.
And when private deployment matters, open-weight models such as Gemma 4 and Mistral Small 4 provide another path entirely.
So before choosing an AI model, ask yourself three questions:
How complex is the task? How much volume will I process? And how much is a better answer actually worth to me?
Once you can answer those questions, navigating dozens of model names and versions becomes much easier.
Most importantly, avoid becoming dependent on a single model.
The AI landscape is changing so quickly that the names at the top of the market may look different again within a few months.
But if you understand what capabilities matter for each type of task, you will still be able to choose the right tool when the next generation of AI models arrives.